

Data Ingestion
Get data reliably from source systems into your platform.
APIs · Databases · Files · Events · StreamingData engineering for reliable decisions
We design and build reliable data ingestion and transformation pipelines that turn scattered data into clean, structured, business-ready information.

What we deliver
From ingestion to curated data, we design, build and modernize the systems that move data reliably through your platform.
Get data reliably from source systems into your platform.
APIs · Databases · Files · Events · StreamingTurn raw data into clean, structured information.
Validation · Enrichment · Deduplication · ModelingStructure data for maintainability, trust and scale.
Bronze · Silver · Gold · Metadata · GovernanceEngineer pipelines for reliable operation in production.
Orchestration · Monitoring · Error handling · Data qualityReplace fragile processes with maintainable infrastructure.
Migrate · Automate · Optimize · ScaleHow we build
A clear, structured approach to turn scattered data into a reliable foundation for analytics and AI.
Learn moreDatabricks · Delta Lake · Unity Catalog
Technical expertise
We combine modern data technologies with proven engineering practices to build scalable and maintainable data platforms.
Engineering
Selected engineering work demonstrating architecture decisions, reusable patterns and production-oriented implementation.
Designed a configuration-driven Databricks validation framework to compare code-freeze pipeline output against production data, detect schema and data-level differences, and surface the impact of business-logic changes before release.
View projectOptimized a SQL-based financial data pipeline with approximately 40 business rules sharing common intermediate results, reducing execution time by 45% through early filtering, improved join strategies and the removal of redundant processing.
View projectMigrated complete enterprise data pipelines from Snowflake and Airflow to Databricks using a controlled pipeline-by-pipeline strategy, Medallion Architecture and old-vs-new data validation.
View projectDesigned and built a SQL Server retail data warehouse integrating multiple transactional MySQL systems, with near-real-time ingestion, a normalized snowflake model and operational reporting for approximately 60 business users.
View projectInsights
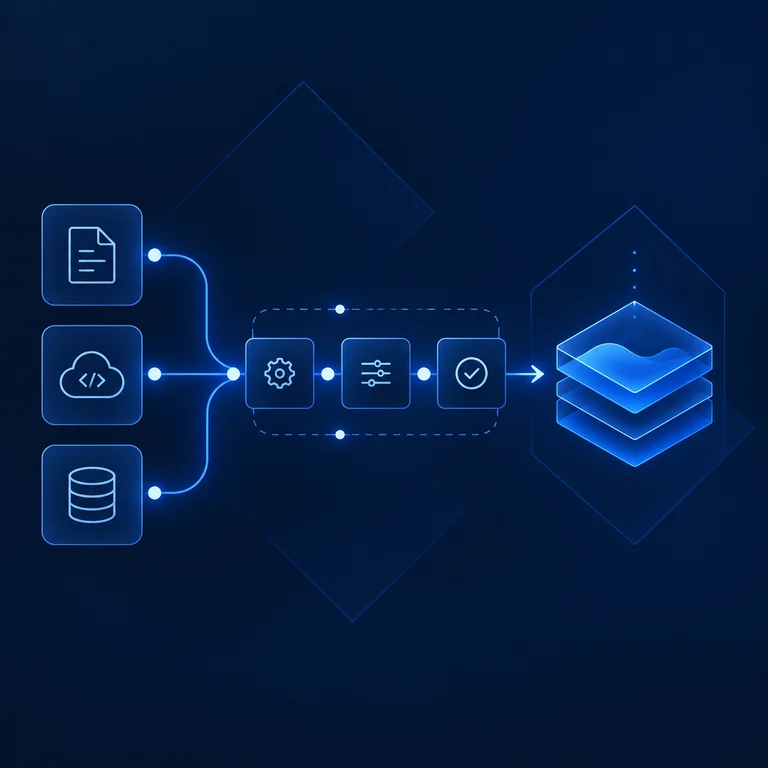
Key patterns and practical considerations for building robust ingestion frameworks.
Read insight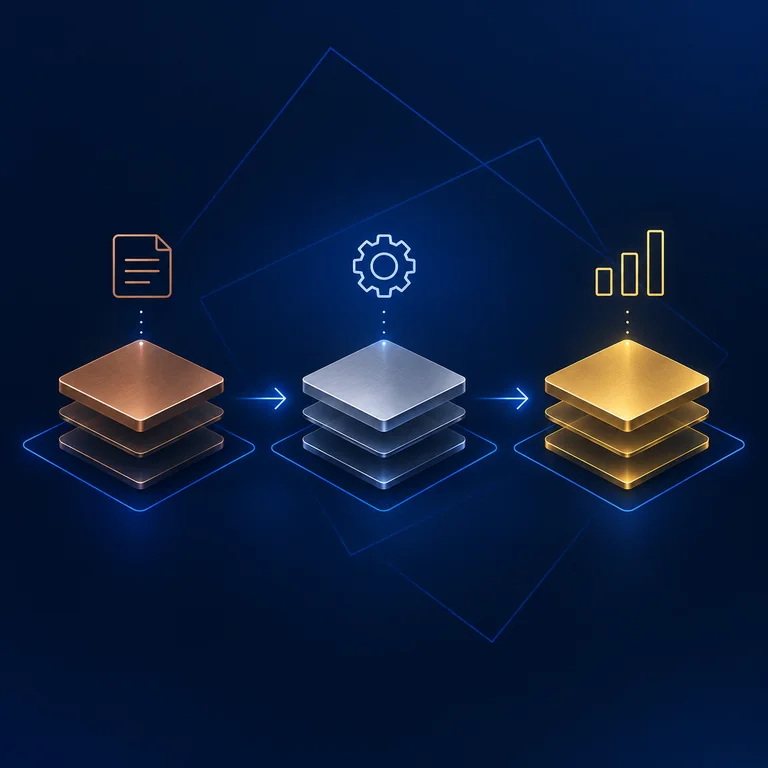
Understanding the Medallion Architecture beyond the basic diagram.
Read insight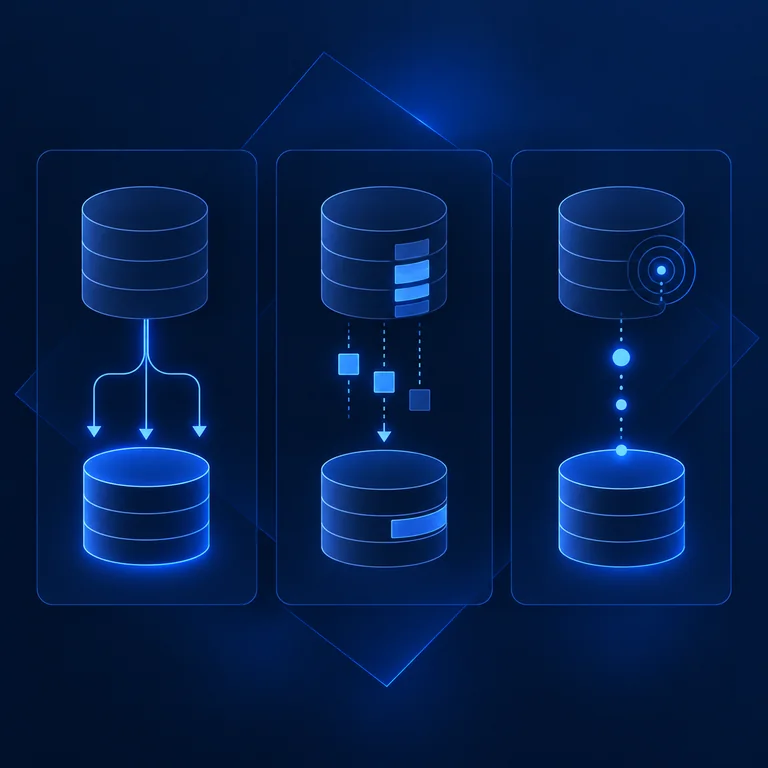
Choosing the right ingestion strategy for your source systems.
Read insightAbout BGP Data Works
BGP Data Works focuses on the data foundation behind analytics and AI: ingestion, transformation, lakehouse architecture and production-grade data pipelines.
Our approach is engineering-led, transparent and practical. We focus on clear architecture, sound technical decisions and maintainable systems that teams can understand and operate. We work with organizations that need to build, modernize or strengthen their data platform — from ingestion pipelines to production-ready lakehouse architectures.
Contact
Tell us about your data sources, pipelines or platform goals. We can start with a focused conversation about the right approach.
Let's talk
Reach us directly by email.


